WarpQuant: Dual-Domain Low-Bit LLM Quantization
A post-training quantization method that reaches INT2/INT3 SOTA accuracy and runs the compressed weights directly through a C++/CUDA llama.cpp kernel — 7.36× faster decoding than GPTQ W3.
WarpQuant is a post-training quantization (PTQ) method for large language models that pushes weights down to INT2 and INT3 without retraining, then executes the compressed payload directly on the GPU through a custom llama.cpp kernel. The point is to connect the two halves that are usually studied separately: how accurate a low-bit model can be, and how fast it actually serves.
This is a summary. The full technical report — method, ablations, and the complete results tables — lives on the WarpQuant project page. Code is on GitHub.
Method
Three ideas combine:
- Signed-Hadamard rotation normalizes weight geometry so the quantizer sees a better-conditioned distribution.
- Output-Fisher sensitivity ranks projections and columns by their effect on next-token loss, so a limited bit budget is spent where it matters.
- Quantized-KFAC recovery restores accuracy at the hardest INT2 setting.
The INT3 payload then runs in a C++/CUDA FLUTE backend inside llama.cpp — the compressed weights are executed directly rather than dequantized to a wider format first.
Results
Accuracy (lower perplexity is better):
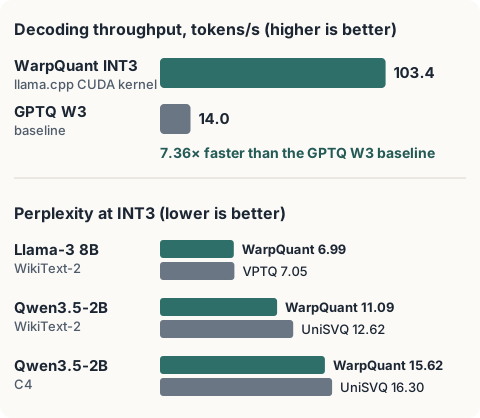
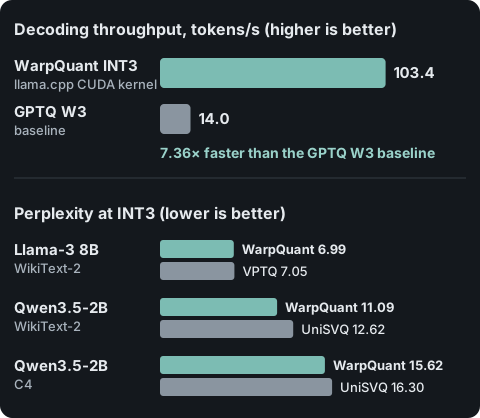
- Llama-3 8B INT3 — WikiText-2 6.99 (VPTQ 7.05)
- Qwen3.5-2B INT3 — WikiText-2 11.09, C4 15.62 (UniSVQ 12.62, 16.30)
- Llama-3 8B INT2 (2.265 bits) — WikiText-2 9.42, C4 13.07
- Mistral 7B (4.139 bits) — WikiText-2 5.42, within 1.1% of the BF16 baseline (5.36)
Serving throughput:
- 103.4 tok/s on the llama.cpp CUDA kernel vs 14.0 tok/s for the GPTQ W3 baseline — a 7.36× speedup. The gain comes from the kernel executing the compressed representation directly, not from using fewer bits per se.
Why it matters
Most quantization papers report accuracy at a bit width and stop. But a format is only useful if there’s a runtime that can serve it quickly. WarpQuant treats the problem end to end — weight representation, bit allocation, accuracy recovery, and native kernel execution — so the compression on paper turns into real decoding throughput.
The full report walks through the complete evaluation and the kernel design.